
Guava today released Daytona, its new voice model, and published the Guava Voice Index, an open scoring framework for voice agent quality. Guava published Daytona’s results alongside the results of three other leading voice AI systems and of live human agents handling the same calls.
This press release features multimedia. View the full release here: https://www.businesswire.com/news/home/20260923955912/en/
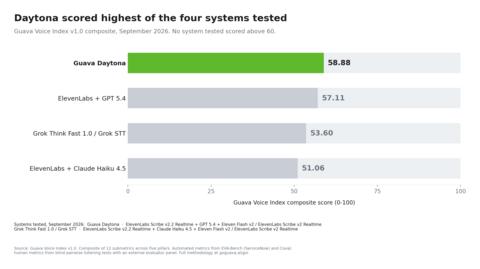
Guava Voice Index v1.0 composite scores, September 2026.Guava Daytona 58.88, ElevenLabs with GPT 5.4 57.11, Grok 53.60, ElevenLabs with Claude Haiku 4.5 51.06.
“Every voice AI company will tell you their agent sounds human. Almost none of them will tell you whether it actually finished the call,” said Omri Dahan, CEO and co-founder of Guava. “We built the index we wanted to exist as buyers, and then we published our own scores on it, including the ones we need to improve.”
The Guava Voice Index scores voice agents from 0 to 100 across five pillars: responsiveness, conversational flow, fidelity, resolution and TTS quality. Content accuracy carries 60 percent of the weight and voice experience 40 percent. The automated layer draws on components of EVA-Bench (1), the voice agent evaluation suite published by ServiceNow, and word error rate measured on Coval’s Voice AI Benchmark (2). The human layer is a blind pairwise test run with an external evaluator panel, with a minimum of ten evaluators per pair. Every system is compared against live human agents handling the same calls, through both audio listening tests and transcript reviews. Guava published the full methodology, the pillar weights and the validation gates at goguava.ai/gvi so the scoring can be examined.
Guava co-founder and Head of Engineering Anthony Scodary put it this way: “Most voice benchmarks are very narrow, for speech-to-text, text-to-speech, or very short toy conversations. The GVI is real conversations with a mix of machine and human evaluators. We believe it’s the new gold standard.”
The four systems tested in September 2026 were Guava Daytona, ElevenLabs paired with GPT 5.4, Grok, and ElevenLabs paired with Haiku 4.5.
Daytona scored highest at 58.88 out of 100, ahead of ElevenLabs with GPT 5.4 at 57.11, Grok at 53.60, and ElevenLabs with Haiku 4.5 at 51.06. No system scored above 60. Daytona led on fidelity and on human-evaluated speech quality and response time. It did not lead everywhere: ElevenLabs with GPT 5.4 scored higher on resolution, 79 percent of available points against Daytona’s 67. Both results are published.
Every system was also measured against live human agents handling the same calls. Evaluators preferred the human agent in 91 percent of comparisons on response timing and 93 percent on interruption recovery, across all four systems tested including Daytona.
Guava builds and operates every model in the stack itself, from speech recognition through to speech synthesis. Guava’s models are trained on more than 10 billion minutes of live agent conversation across 100+ production deployments since 2013. The company is SOC 2 Type II Certified, HITRUST i1 Certified, and PCI DSS Level 1 Compliant, with BAAs available for healthcare deployments.
Daytona is available to Guava customers today. The Guava Voice Index and the full leaderboard are published at goguava.ai/gvi and will be updated as new systems are tested.
About Guava
Guava is where your expertise finds its voice. One stack spanning speech recognition, language, speech synthesis, dialog control, compliance, and supervision, with 100+ deployments since 2013 and customers live within 14 days of kickoff. SOC 2 Type II, HITRUST i1, PCI DSS Level 1. Learn more at goguava.ai.
References
- EVA-Bench: A New End-to-end Framework for Evaluating Voice Agents. https://arxiv.org/abs/2605.13841
- Coval Voice AI Benchmarks. https://benchmarks.coval.ai/overview
View source version on businesswire.com: https://www.businesswire.com/news/home/20260923955912/en/
Media gallery


